

AI Development Process: Enterprise Lifecycle Guide for 2026

The most popular advice about the AI development process is incomplete. Teams are told to choose a model, prepare data, train it, and deploy it. That sequence describes a prototype, not an enterprise system. The difficult work usually begins after the training run succeeds, when engineers must prove that the model is reliable, integrate it with legacy systems, create review capacity, and define what happens when it fails.
AI has moved through distinct technical eras. The first mathematical neuron model appeared in 1943, the Dartmouth workshop formally named the discipline in 1956, AlexNet marked a deep-learning inflection point in 2012, and the Transformer architecture emerged in 2017, according to the World Economic Forum's history of AI. Those milestones explain why modern teams need more than model expertise. They need data engineering, software delivery, security, compliance, and operational ownership working as one lifecycle.
Table of Contents
Why Most AI Projects Stall After Training - The prototype to production gap
Building a Gated Data Strategy and Governance Pipeline - Build the pipeline around gates
Model Design and Training with Evaluation Integrity - Protect the evidence - Make evaluation reproducible
Deployment Patterns and MLOps Integration - Redesign software delivery gates
Monitoring and Risk Management at Scale - Define autonomy before incidents occur
Enterprise AI Development Maturity Checklist - Data readiness - Model and evaluation integrity - Delivery and operations - Governance in production
Why Most AI Projects Stall After Training
Training is visible, measurable, and technically impressive. Production readiness is fragmented across teams, which makes it easier to underestimate. A model can perform well in a notebook and still fail when its inputs arrive late, its outputs require human review, or its predictions conflict with a business process that was never designed to consume them.
The modern field began as a small, rule-driven research effort. Christopher Strachey wrote an early successful AI program for the Ferranti Mark 1 in 1951, while the term artificial intelligence appeared in the 1955 Dartmouth Summer Research Project proposal. AlexNet's 2012 ImageNet result helped shift the field toward large labeled datasets, and the Transformer later changed how language systems were developed and scaled. The IBM history of artificial intelligence places these milestones in the longer transition from symbolic systems to deep learning and foundation models.
The prototype to production gap
A trained model isn't a product. It becomes a product only when the organization can answer practical questions:
Input ownership: Which system supplies the data, and who investigates missing or corrupted inputs?
Output accountability: Who can approve, reject, or override a recommendation?
Release evidence: Which tests must pass before the model reaches users?
Failure handling: What does the application do when confidence falls, latency rises, or the model produces unsafe content?
Change control: How are model, prompt, data, and dependency changes recorded?
These questions expose the bottleneck. Recent developer data reports that AI-generated pull requests wait 4.6 times longer for first review and are accepted at 32.7%, compared with 84.4% for human-written pull requests. The same source reports that 43% of AI-generated code that passes quality assurance or staging still needs manual debugging in production, as documented by AI Beavers' analysis of developer AI usage gaps.
Practical rule: Treat every lifecycle stage as a release gate, not as a handoff to the next specialist.
The enterprise AI development process therefore has two parallel tracks. The technical track covers data, architecture, training, serving, and monitoring. The control track covers provenance, evaluation integrity, access, human oversight, auditability, and rollback. Projects stall when the first track moves quickly while the second remains informal.
The World Economic Forum described AI in 2024 as “racing ahead” and reported a claim that it was getting “twice as powerful every six months,” reflecting the pace of frontier development cycles. That pace makes governance more important, not less. A faster model pipeline can produce more unreviewed code, more frequent model changes, and more operational risk unless review capacity grows with it.
Building a Gated Data Strategy and Governance Pipeline
Data preparation shouldn't begin with “collect everything.” It should begin with the target behavior, the permitted data sources, and a measurable decision about whether a dataset improves the system. Recent benchmark work separates data construction from data quality evaluation, then tests both against downstream training utility rather than surface-level text quality. The distinction matters because clean-looking examples can still fail to improve the target model after fine-tuning.
Build the pipeline around gates
Start with raw data ingestion, but don't allow ingestion to imply approval. Store the source, collection context, transformation history, access classification, and intended use for every material dataset. The team responsible for data engineering should be able to reproduce how raw records became training examples.
A workable gated flow looks like this:
Ingest and register: Capture source ownership, provenance, licensing or permission context, schema, and sensitive-data classification.
Construct examples: Transform approved raw material into supervised fine-tuning examples or other task-specific records.
Run quality checks: Test completeness, duplication, formatting, label consistency, representativeness, and policy constraints.
Measure training utility: Fine-tune a controlled candidate model and compare downstream behavior against a baseline.
Approve or reject: Record the decision, reviewer, evidence, and restrictions before the dataset enters an expensive training run.
Data construction and quality evaluation should remain separate controls. Construction asks whether the examples represent the task correctly. Quality evaluation asks whether those examples help the model perform the task. Combining both into a single “clean data” score hides the question that matters most to an engineering budget, whether the data improves the intended system.
The benchmark work spans six domains and multiple base models, showing that data-preparation performance can vary materially by domain and model family. Enterprise teams shouldn't assume that a curation method that works for customer support will work for legal documents, financial records, or multilingual content.
For teams formalizing the control layer, this overview of what is information governance provides useful context on how organizations manage information through its lifecycle. In practice, governance means assigning decision rights, not merely storing policy documents.
The image above should not be duplicated in an implementation. The operational equivalent is a registry that blocks promotion when provenance is missing, contamination checks fail, or the dataset's measured utility doesn't justify its use. Teams dealing with fragmented sources can also review this data integration challenges visual as a prompt for mapping ownership and dependencies.
A final control is contamination prevention. Benchmark examples must not leak into training data, because leakage makes evaluation unreliable and can artificially inflate performance numbers. Provenance tracking, dataset versioning, access controls, and pre-release contamination checks should be mandatory before a release candidate is selected.
Model Design and Training with Evaluation Integrity
Model selection should follow the task and its constraints, not the popularity of an architecture. A small model may be easier to serve, inspect, and constrain. A larger foundation model may offer stronger general capabilities but introduce higher infrastructure, latency, cost, and governance demands. The right choice is the model that satisfies the business objective under the organization's operational limits.
The Transformer architecture, which emerged in 2017, became foundational to many modern large language models. Its importance isn't just historical. It represents the shift toward systems that can be trained and scaled for broad language tasks, which is why model design now includes decisions about pretraining, fine-tuning, retrieval, instruction behavior, serving, and evaluation.
Protect the evidence
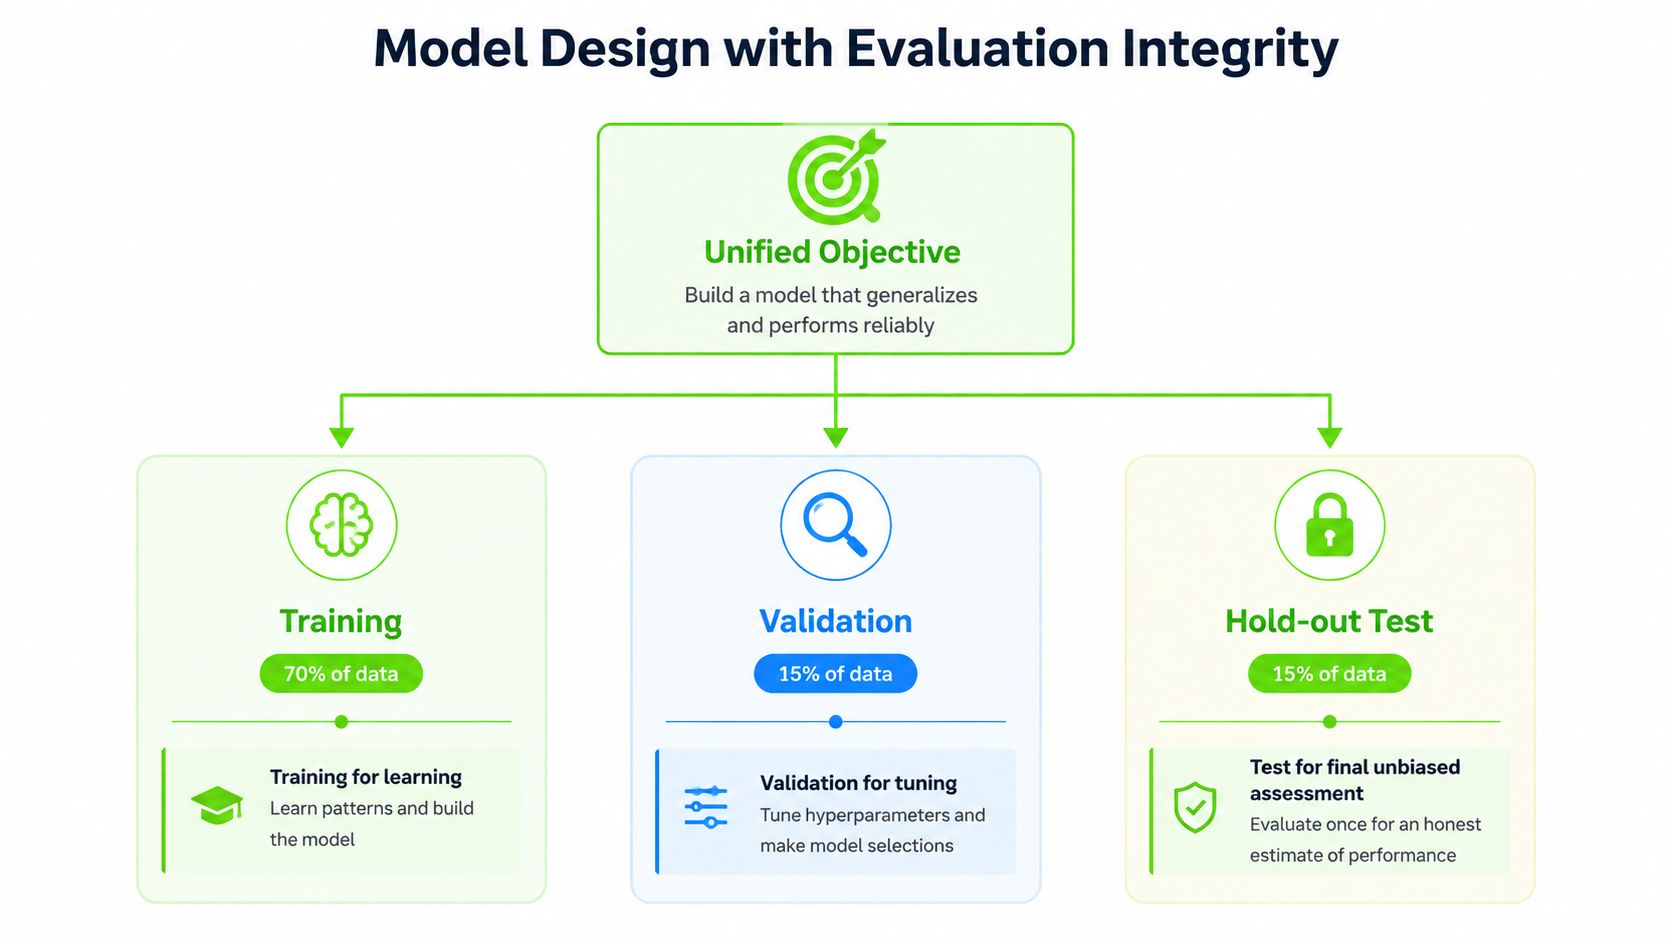
Use separate training, evaluation, and test partitions. Training data teaches the model. Evaluation data supports tuning and iteration. The hold-out test set provides the final assessment after design choices are fixed. A separate golden dataset of trusted input-output pairs gives reviewers an objective reference for comparing candidate versions during development.
Don't tune repeatedly against the same data used for final validation. That practice rewards memorization and makes overfitting harder to detect. The final test set should remain protected from routine experimentation, with access limited to the people and systems responsible for release assessment.
Benchmark design must also match the system's real duties. Government guidance describes commercial developers using benchmark tests to evaluate reasoning, factuality, mathematics and science, and multilingual comprehension, alongside red teaming and multidisciplinary review. Those dimensions should be selected because they represent actual risk or value, not because they make a release report look thorough.
Make evaluation reproducible
A serious evaluation package includes:
Task metrics: Define the measures that reflect the intended output, including correctness, refusal behavior, consistency, or human acceptance where appropriate.
Golden examples: Maintain trusted input-output pairs that reviewers can inspect and version.
Adversarial cases: Test prompt injection, ambiguous instructions, unsafe requests, sensitive information, and boundary conditions.
Review records: Store the model version, data version, evaluator, test results, and release decision.
Contamination checks: Confirm that benchmark material hasn't entered training or tuning data.
Evaluation integrity is a governance property as much as a statistical one. A model that scores well on contaminated benchmarks may look ready while remaining fragile in production. The release committee should ask not only “What score did it achieve?” but also “Can we prove that the score reflects unseen behavior?”
Training itself should be treated as an experiment with controlled inputs. Record hyperparameters, base-model versions, prompt or instruction templates, retrieval configuration, and infrastructure assumptions. When a result changes, the team should know whether the cause was data, architecture, tuning, evaluation, or serving.
Deployment Patterns and MLOps Integration
Production deployment is where machine learning meets ordinary software engineering. The model needs a stable runtime, an interface, authentication, observability, capacity planning, and a rollback path. A model endpoint without these controls is a demonstration, not a dependable service.
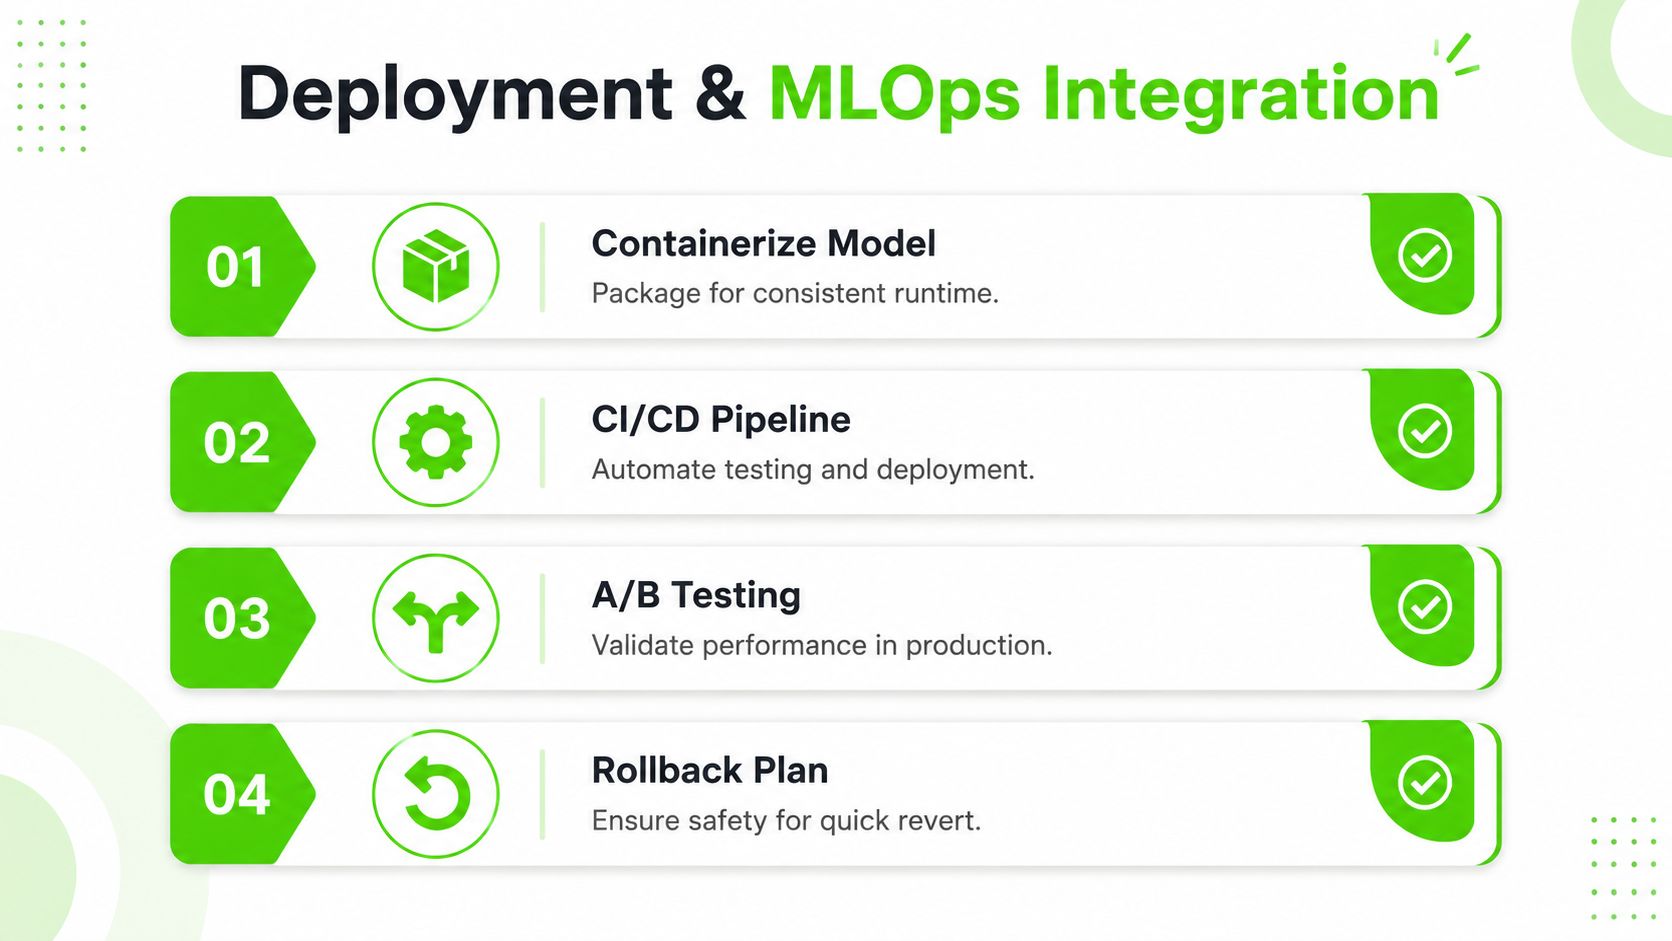
Containerize the serving environment so engineers can reproduce dependencies across development, staging, and production. For feature-based systems, a feature store can help align training and inference inputs. For language systems, teams may need versioned prompts, retrieval indexes, safety filters, and structured output validation. Continuous training should never mean continuous automatic promotion. It should mean that new data can trigger a controlled evaluation and approval path.
Redesign software delivery gates
AI-assisted coding changes the volume and shape of review work. Only 37% of developers using AI at the build stage describe their maturity as “formal or better,” and 51% report that AI breaks on legacy code, according to AI Beavers' developer usage analysis. The response shouldn't be to ban acceleration. It should be to move verification earlier and make ownership explicit.
A practical CI/CD path can include:
Static and dependency checks: Scan generated code, packages, secrets, and licensing risks.
Behavioral tests: Verify model outputs against golden cases and known failure modes.
Contract tests: Confirm that APIs, schemas, feature definitions, and downstream consumers remain compatible.
Staged release: Use a limited production exposure or controlled comparison before wider availability.
Rollback automation: Revert the model, prompt, retrieval index, or code package independently when possible.
Engineers responsible for deployment should distinguish code changes from model changes. They may share a delivery platform, but they require different evidence. A code release can pass unit tests while a model release changes refusal behavior, latency, or performance on a particular domain.
Teams that want a practical reference for deploying models with DataTeams can use it to compare serving patterns and operational responsibilities. Internal architecture documentation should then define which pattern applies to each workload.
The central trade-off is speed versus reversibility. A fast deployment that can't be rolled back safely creates operational debt. A cautious pipeline with automated checks, clear ownership, and reversible releases can support frequent change without turning every update into a compliance emergency. Teams exploring broader enterprise patterns can also consult this enterprise AI solutions guide.
Monitoring and Risk Management at Scale
Deployment doesn't finish the AI development process. It starts the phase that lasts longest and often receives the least engineering attention. A production model can degrade because input distributions change, upstream systems alter fields, users discover unexpected interactions, or business rules move beyond the data used during development.
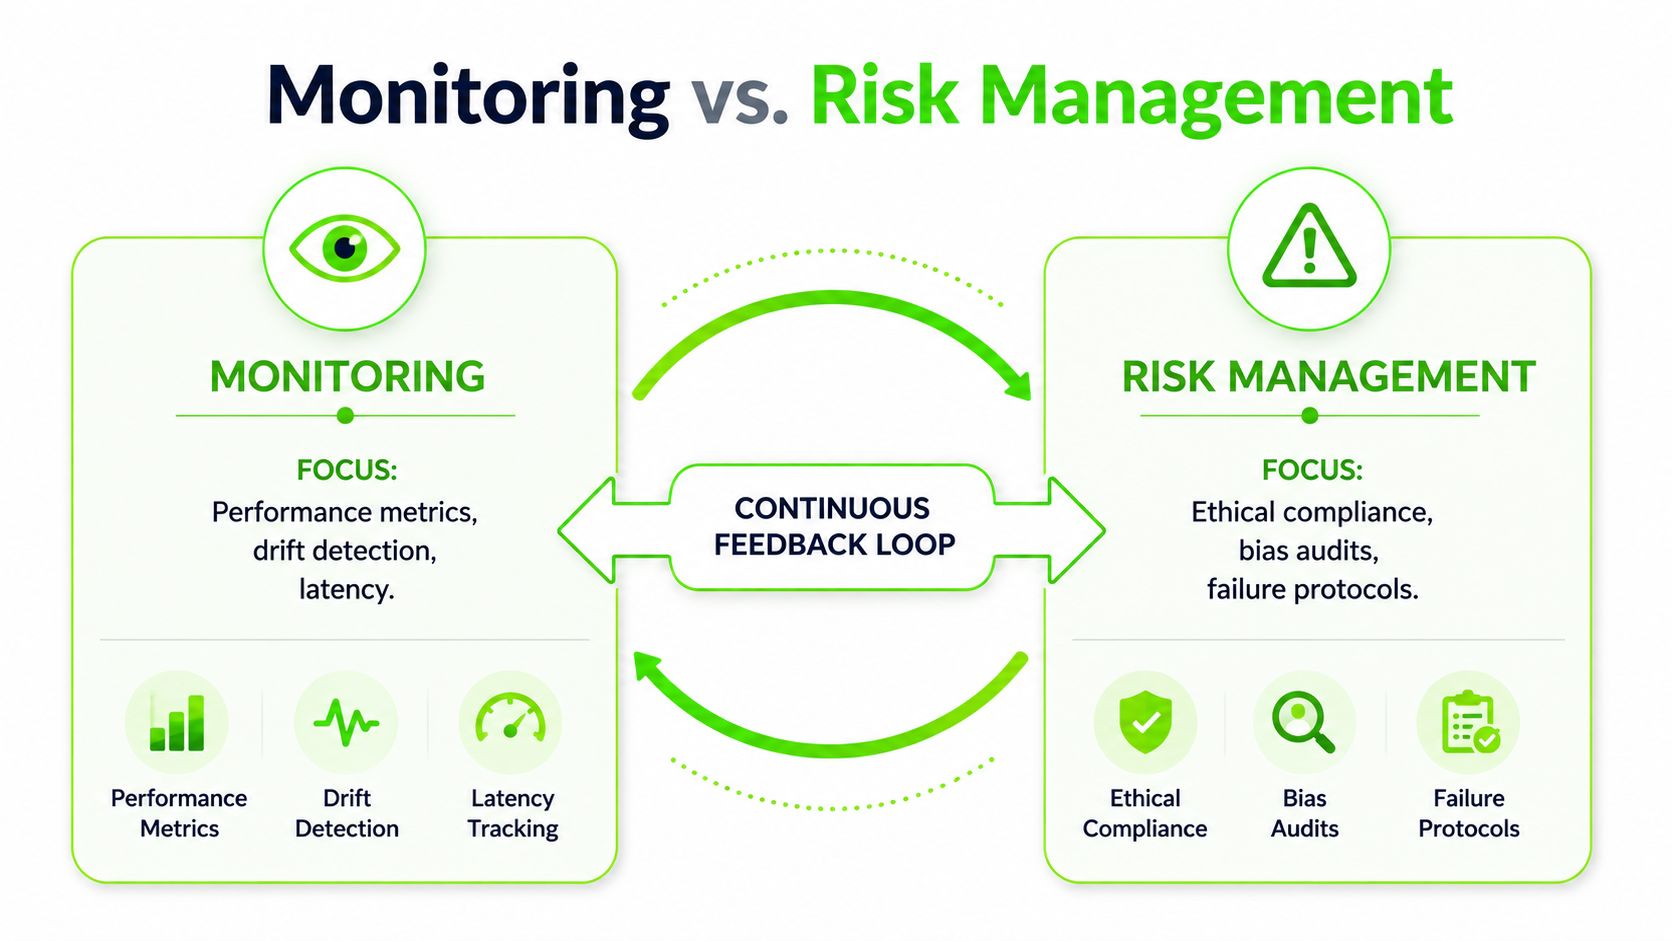
Monitoring should cover technical health and decision quality. Track latency, availability, throughput, input completeness, output structure, drift signals, refusal behavior, and escalations. The exact dashboard depends on the use case, but every metric needs an owner and an action threshold. A metric without a response plan is decoration.
Define autonomy before incidents occur
“Human in the loop” is too vague to operate. Teams need to define what the human reviews, when review is mandatory, and what the system can do without approval.
Useful policy boundaries include:
Draft-only autonomy: The system may generate content or recommendations, but a named role must approve every external action.
Threshold-based autonomy: The system can proceed only when confidence, data quality, and policy checks meet defined conditions.
Exception routing: Ambiguous, sensitive, or high-impact cases go to a specialist queue with a response target.
Read-only access: The agent can retrieve information but can't modify records or trigger transactions.
Emergency stop: An owner can disable the workflow without waiting for a model retraining cycle.
These boundaries should vary by harm, reversibility, and data sensitivity. A marketing draft and a financial decision shouldn't share the same autonomy policy. Compliance officers, product owners, security teams, and domain specialists should agree on the thresholds before launch.
Enterprise adoption illustrates the operational gap. Research reports that 71% of companies are actively using or piloting AI, while only about 30% feel fully prepared to operationalize it end to end, according to Serious Insights' enterprise AI update. That gap exists because experimentation is easy to authorize, while production governance requires durable ownership, evidence, and escalation.
Monitoring and risk management must form a feedback loop. An incident should update tests, training data, policies, and reviewer guidance. Security assessments also belong in this loop, and teams can use this cloud security assessment visual when mapping infrastructure and access risks.
How AI-Native Agencies Outperform Traditional Workflows
Traditional agencies often organize work around sequential handoffs. Research, briefing, production, review, reporting, and optimization happen in separate stages, which can make coordination expensive and slow. AI-native agencies organize the same work as connected workflows, using models, structured data, reusable agents, and automated checks to compress the distance between decision and execution.
Freeform states that it was established in 2013, before “marketing AI” became a buzzword, and frames that early start as part of its pioneering role in marketing AI. That history supports its position as an industry leader with an operating model built around AI-enabled marketing rather than a recent layer added to a traditional agency process. Its practical advantages are enhanced speed, cost-effectiveness, and superior results, provided the workflows retain human review and measurable controls.
A 2026 industry analysis reports hours-to-launch workflows for production-heavy paid-media and content work, compared with weeks in traditional agency processes. It gives examples of market research moving from 2–4 weeks to 2–4 hours and monthly reporting moving from 3–5 days to real time, as documented by Soku's comparison of AI and traditional marketing agencies.
Metric | Traditional Agency | AI-Native Agency |
|---|---|---|
Market research | 2–4 weeks | 2–4 hours |
Monthly reporting | 3–5 days | Real time |
Production model | Sequential handoffs | Connected workflows |
Cost structure | More manual production effort | More automation and reusable systems |
Optimization | Periodic review | Continuous, governed iteration |
Independent reporting cites use cases with 44% ROAS increases, 31% revenue growth, and 72% lower cost-per-order when AI is properly deployed. It also cites 300% average ROI in marketing teams implementing AI, though these figures are use-case claims rather than a guarantee for every campaign, as described by Articsledge's AI marketing agency analysis.
The evaluation standard should be operational, not theatrical. Ask an agency how it handles approval thresholds, source data, brand controls, model changes, and campaign rollback. Technologies such as serverless GPU agents can support flexible AI workloads, but infrastructure alone doesn't create a reliable marketing system. Freeform Company offers custom AI agent development, including discovery and strategy, design and prototyping, development and integration, testing and refinement, and deployment and optimization.
Enterprise AI Development Maturity Checklist
A mature AI program can answer “yes” to operational questions, not just technical ones. Use the checklist below in a cross-functional review, then assign each gap to a named owner. Data engineers, ML engineers, MLOps teams, security specialists, compliance officers, and product leaders should leave the meeting with decisions rather than general agreement.
Data readiness
Provenance is recorded: Every production dataset has a source, owner, transformation history, access classification, and permitted-use decision.
Utility is measured: Candidate data is evaluated against downstream training performance, not only formatting or surface-level quality.
Contamination is checked: Benchmark and golden examples are protected from unauthorized inclusion in training or tuning data.
Rejection is possible: The pipeline can block a dataset when quality, compliance, or provenance evidence is incomplete.
Model and evaluation integrity
Partitions are separated: Training, evaluation, and hold-out test data serve different purposes and aren't reused casually.
Golden data is protected: Trusted input-output pairs support objective comparisons across versions.
Failure modes are tested: Red teaming covers misuse, ambiguity, sensitive information, and domain-specific hazards.
Review is multidisciplinary: Technical, product, security, and compliance reviewers can challenge the release evidence.
Delivery and operations
The runtime is reproducible: Dependencies, model artifacts, prompts, retrieval components, and configuration are versioned.
CI/CD tests AI behavior: Automated delivery checks include model validation, contracts, safety cases, and integration tests.
Rollback is rehearsed: The team can revert a model or related component quickly and knows who can authorize it.
Drift has an owner: Input changes, output changes, latency, and data quality signals route to specific responders.
Governance in production
Autonomy is explicit: Policies define what the system may draft, recommend, approve, modify, or trigger.
Human review has thresholds: High-risk, low-confidence, sensitive, or exceptional cases follow a documented escalation path.
Data handling is enforced: Access, retention, logging, and approved-use rules are implemented in systems, not left to individual memory.
Value is measured clearly: Product teams track whether the system improves the intended workflow without hiding review effort or downstream defects.
Start with the first failed gate, not the most fashionable model upgrade. If review capacity is the bottleneck, improve the SDLC. If evidence is weak, protect the evaluation system. If autonomy is unclear, narrow the action boundary before expanding deployment. That sequence turns the AI development process into an operating discipline rather than a series of disconnected experiments.
Freeform Company helps enterprises connect custom AI agent development with testing, integration, deployment, compliance, and ongoing optimization. Visit Freeform Company to explore practical guidance and services for building faster AI workflows without losing production readiness or governance control.